Explore 12,000+ niche markets with no login required
TL;DR
LLM tracking tools in 2026 include Dageno AI, Profound, Ahrefs Brand Radar, Scrunch and Bluefish; SEO teams should compare retained answers, citation evidence and competitor analysis on a stable prompt set.
This guide covers brand visibility in AI search: mentions, citations, recommendations, sentiment, and the evidence behind observed answers. It does not compare developer tracing or application-observability tools.
The nine products compared for AI-search marketing in 2026 are Dageno AI, Profound, Ahrefs Brand Radar, Scrunch, Bluefish, Peec AI, OtterlyAI, Semrush, and SE Visible. Choose according to prompt discovery, answer history, citation research, competitor analysis, and reporting needs.
Best LLM tracking tools at a glance
These nine platforms cover different research and monitoring workflows; compare the underlying answers and sources before choosing by an aggregate visibility score.
Rank
Tool
Best for
Main strength
1
Dageno
SEO and content teams that need action, not only reporting
Prompt opportunities, citations, competitors, crawler data, and content workflow
2
Profound
Enterprise answer intelligence
Large-scale prompt, answer, source, and market analysis
3
Ahrefs Brand Radar
Research tied to an established SEO dataset
Brand, topic, source, web, and AI visibility research
4
Scrunch
Enterprise brand accuracy and AI accessibility
Brand representation, knowledge, and agent-readiness context
5
Bluefish
Audience-level enterprise measurement
Custom audiences, accuracy, source impact, GEO, and commerce
6
Peec
Clear, focused stakeholder reporting
Visibility, sentiment, sources, and competitor views
7
Otterly
Small-team monitoring pilots
Straightforward prompt, mention, link, and citation tracking
8
Semrush
Existing SEO-suite users
AI visibility within a broader search workflow
9
SE Visible
SE Ranking users and agencies
Accessible brand, competitor, and trend reporting
Short answer: Dageno is the best overall fit when a team needs to discover AI-search demand, diagnose missing mentions or citations, and decide which content to improve. Profound and Bluefish are stronger candidates for complex enterprise programs. Ahrefs Brand Radar is compelling for large-scale research, while Peec, Otterly, Semrush, and SE Visible can be easier to fit into a focused or existing workflow.
What “LLM tracking” means in this guide
This article covers brand visibility in AI search, not engineering observability for an LLM application. A marketing-focused LLM tracker monitors generated answers to questions relevant to your market. An application-observability platform monitors latency, token cost, traces, evaluations, and failures inside software your company built. The two categories solve different problems.
For AI search, tracking usually includes:
Answer presence: did the brand appear at all?
Mention rate: how often did the brand appear across a defined prompt set?
Recommendation position: where was the brand placed in a comparison or list?
Citation rate: did the answer link to the brand’s site?
Source attribution: which first- or third-party URLs influenced the answer?
Share of voice: how often did the brand appear relative to named competitors?
Sentiment and narrative: how was the brand described?
Accuracy: did the answer contain outdated or incorrect facts?
Trend: did these outcomes change across repeated, comparable runs?
No platform can see every private prompt typed by every user. Most products work with controlled prompt sets, research datasets, inferred demand, or a combination. Treat every score as a sample, and require the prompt, answer, model, date, market, and denominator behind it.
How we evaluated the tools
We compared the platforms using criteria that match the page’s highest-impression Search Console queries:
Ability to preserve the exact text generated by an AI engine.
Brand and competitor mention tracking.
Citation and source-level attribution.
Explanation of why a competitor appears more often.
Visibility, citation rate, share of voice, sentiment, and recommendation metrics.
Prompt research and coverage beyond a manually entered list.
Alerts when brand visibility or accuracy changes.
Hallucination and factual-accuracy workflows.
Market, language, model, and historical segmentation.
Clear next actions for SEO, content, PR, or product data.
Vendor coverage and packaging change frequently. Confirm current engines, countries, languages, limits, retention, exports, integrations, and prices on each official site before purchasing.
1. Dageno: best overall LLM tracking workflow
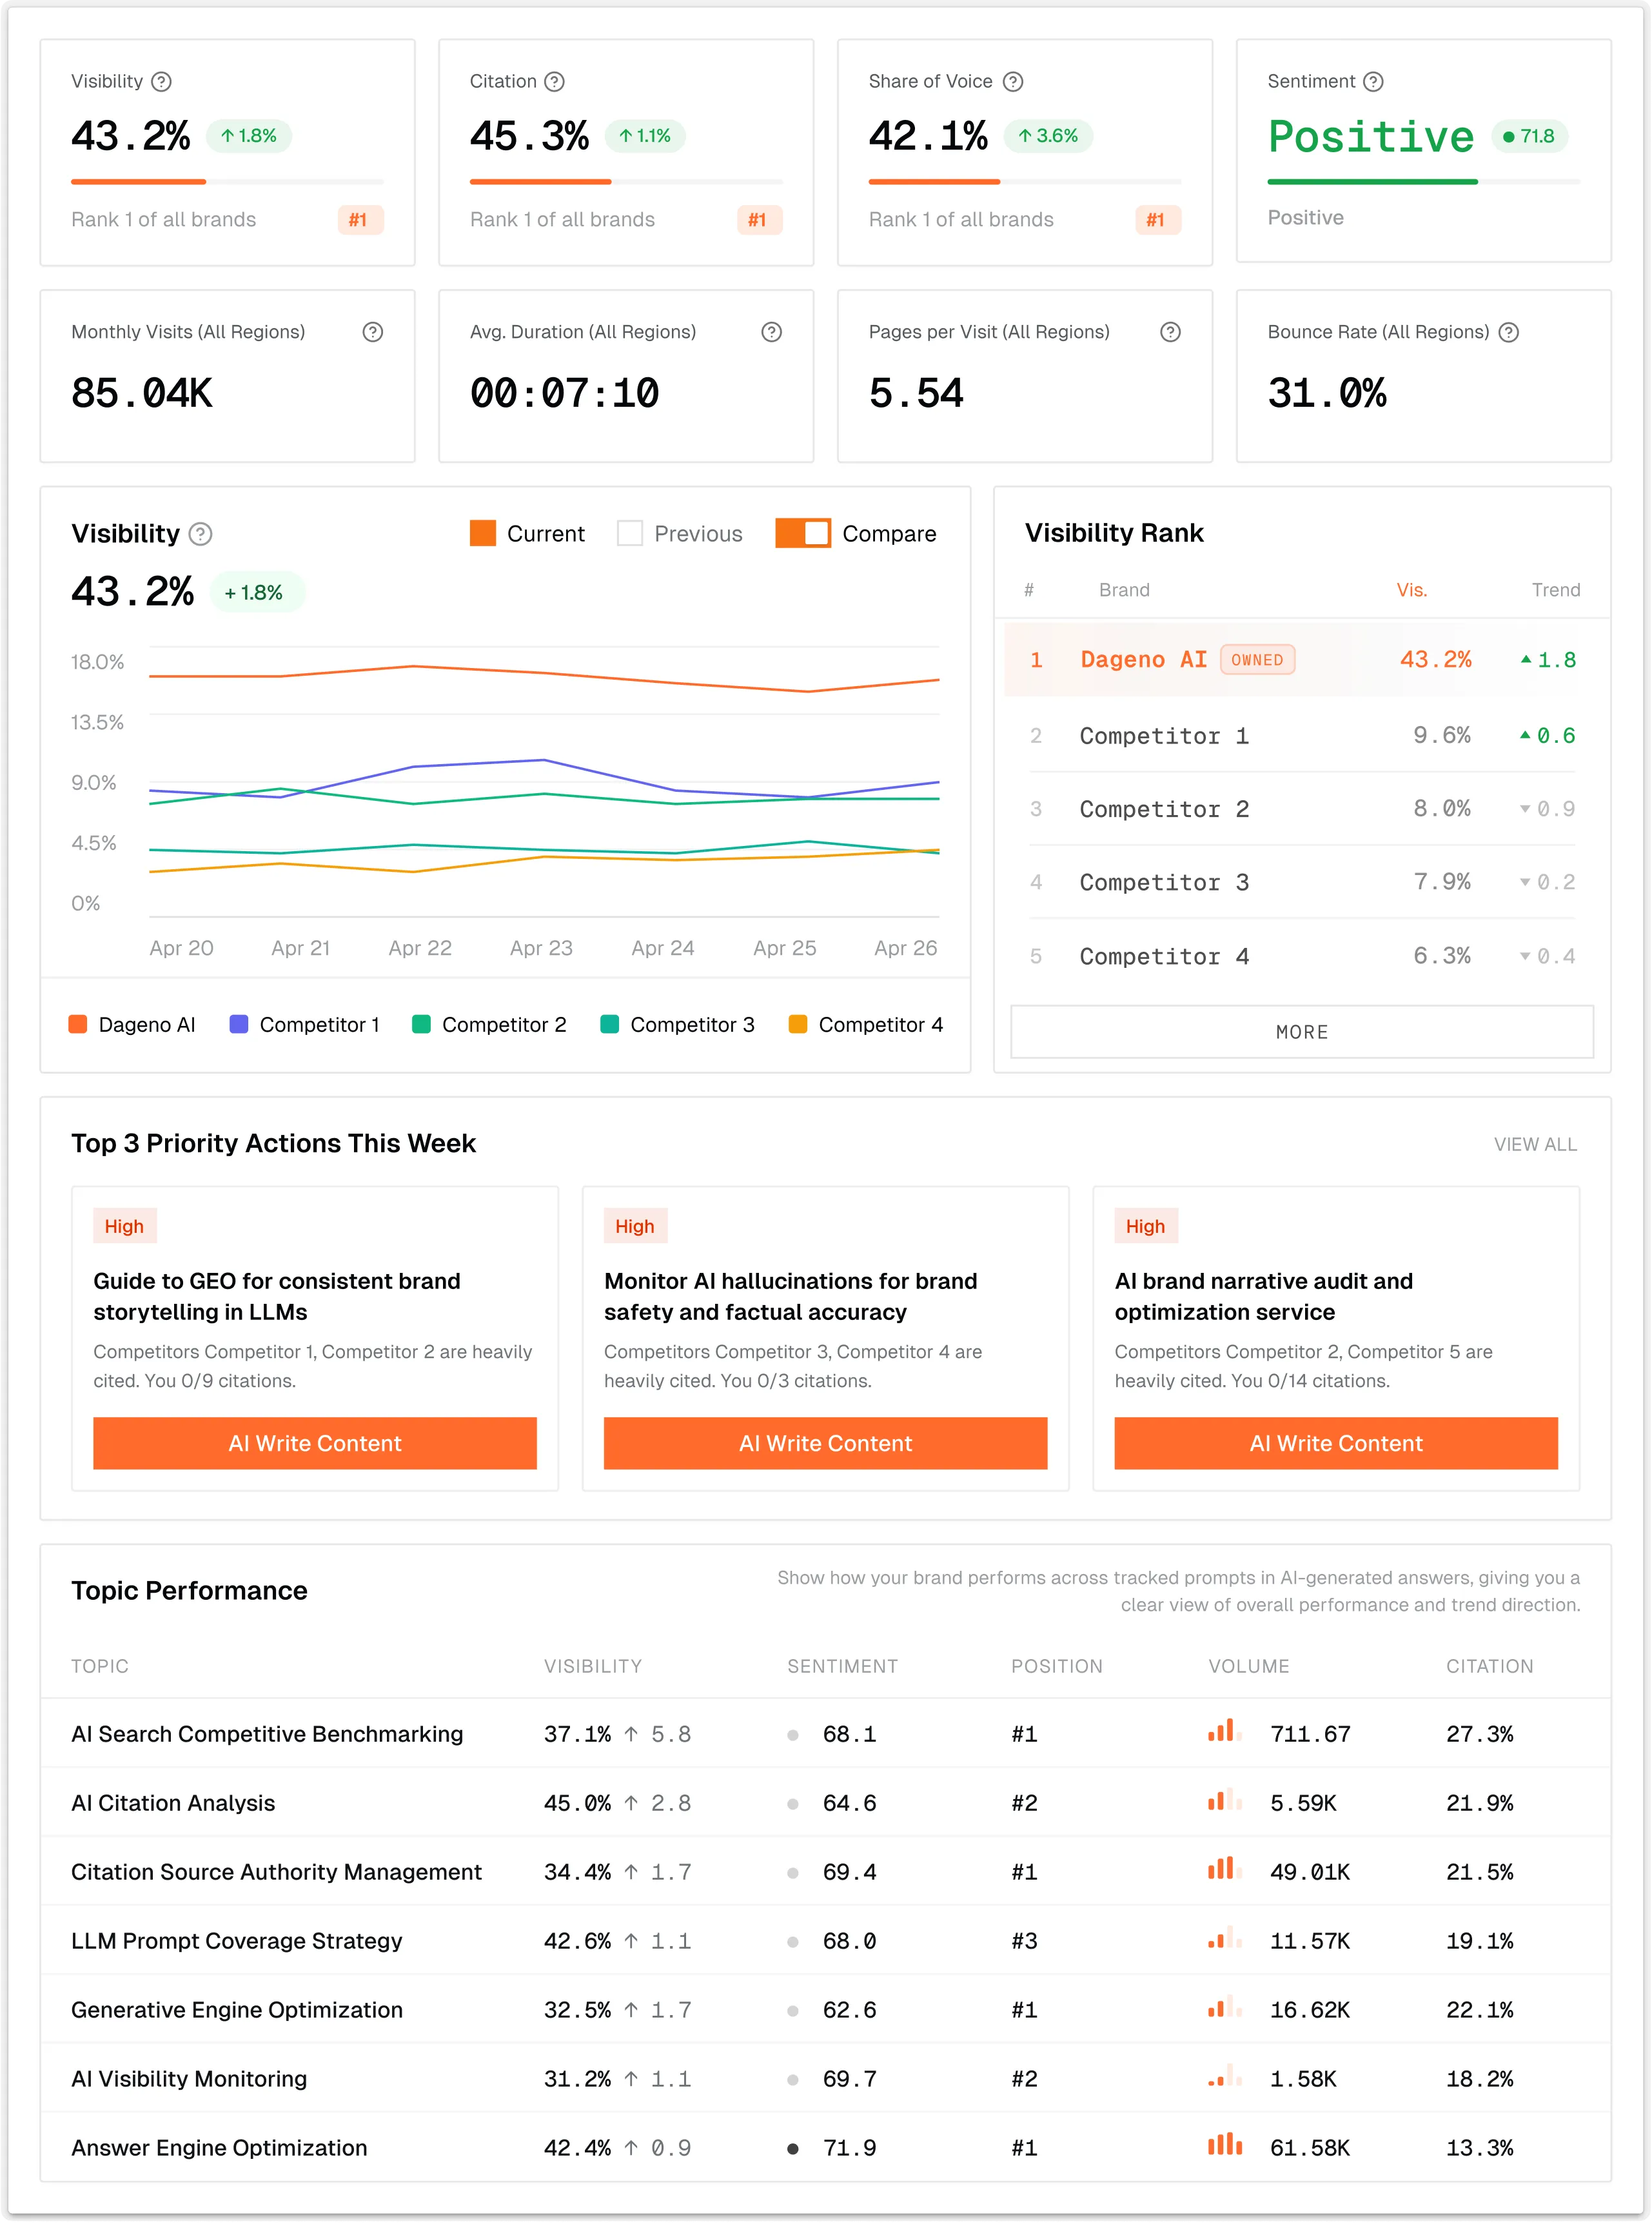
Dageno connects AI-search monitoring with the work required to improve performance. Teams can review visibility, share of voice, sentiment, cited sources, prompt-level gaps, and competitor wins, then turn those findings into content and authority-building priorities. Dageno's BotSight Analytics adds a separate view of AI crawler visits using server logs. Compare crawler activity with answer-level evidence; a crawler visit alone does not prove that a page was cited.
The key advantage is diagnostic depth. Instead of ending at “competitor X appears more often,” the workflow can identify the prompt cluster, the answer evidence, the source gap, and the owned page that needs work. This makes Dageno particularly useful for SEO, content, digital PR, and growth teams sharing one AI-search program.
Best for: teams that need monitoring, prompt opportunities, citation diagnosis, and execution in one workflow.
Watch for: Dageno complements rather than replaces a backlink index, web analytics platform, technical crawler, or media database. Confirm the exact models and markets included in your plan.
Use prompt and citation evidence to assign a specific content action, then record its completion and inspect later results against the same baseline.
2. Profound: best for enterprise answer intelligence
Profound is designed for organizations that want broad AI-answer research across prompts, markets, models, competitors, and sources. It is a strong shortlist option when analysts need to distribute intelligence across brand, content, communications, and leadership teams.
Its enterprise positioning is an advantage when governance and research scale matter. It can be more platform than a small team needs, so evaluate it with a realistic prompt taxonomy and a reporting workflow rather than a generic dashboard demonstration.
Best for: large organizations with dedicated AI-search analysts and cross-functional reporting requirements.
Watch for: verify data retention, prompt methodology, country coverage, exports, service levels, and total contract cost.
Ahrefs Brand Radar brings AI visibility into a familiar search and web-research environment. It is useful when the team wants to investigate brand mentions, competitors, topics, cited pages, and broader web demand without separating AI research from its existing SEO dataset.
This is particularly valuable for answering “Which sources and topics consistently support the competitors that AI recommends?” The research still needs an experimentation plan: a large dataset does not prove why an answer changed.
Best for: Ahrefs customers and SEO researchers who need broad market context.
Watch for: confirm which AI surfaces, regions, historical periods, and source types are included in the purchased package.
4. Scrunch: best for brand accuracy and AI accessibility
Scrunch combines answer monitoring with the information and technical layers that influence how AI agents understand a brand. That makes it relevant when the problem is not only low mention share, but also incorrect product facts, entity confusion, or pages that AI systems cannot interpret reliably.
Best for: enterprise brand, web, and SEO teams working on representation and agent readiness.
Watch for: confirm how the platform distinguishes observed citations, inferred influence, technical accessibility, and factual accuracy.
5. Bluefish: best for audience-level enterprise tracking
Bluefish organizes AI performance around audiences, topics, sources, favorability, safety, accuracy, and products. Its custom-audience methodology is useful for enterprises that need to understand not only whether a brand appears, but for which buyer context it appears and which narrative influences that result.
Bluefish also documents GEO recommendations, source-impact analysis, brand-data verification, and agentic-commerce features. Pricing is not publicly standardized, so evaluation begins through its sales process.
Best for: global brands with audience segmentation, governance, brand-accuracy, or shopping-AI requirements.
Watch for: request a written coverage matrix and verify prompt methodology, integrations, data controls, and total implementation cost.
Peec offers a dedicated interface for monitoring AI visibility, sentiment, cited sources, and competitors. It is a sensible option when a lean marketing team or agency needs understandable reports without a broad enterprise transformation project.
Best for: agencies, consultants, and marketing teams that prioritize reporting clarity.
Watch for: test the exact models and markets you need, and confirm whether the workflow leads from a finding to a page-level action.
7. Otterly: best for a straightforward monitoring pilot
Otterly focuses on prompt monitoring, mentions, links, citations, and competitive visibility. Its narrower workflow is useful for establishing a baseline and learning which reports stakeholders will actually use before committing to a larger system.
Best for: small teams and consultants running a controlled AI-search pilot.
Watch for: enterprise permissions, localization, attribution, integrations, and reporting depth may require another product or process.
Semrush is attractive when an organization already uses the suite for keywords, competitors, backlinks, and content work. AI visibility reporting can fit into an existing procurement and operating model instead of introducing a separate specialist vendor.
Best for: generalist SEO teams and existing Semrush customers.
Watch for: compare its raw-answer access, prompt sampling, source granularity, and market coverage with a dedicated AI-search tracker.
SE Visible tracks brand and competitor visibility across AI search surfaces within the SE Ranking ecosystem. It is practical for agencies that value consolidated reporting and a familiar interface.
Best for: agencies and teams already using SE Ranking.
Watch for: buyers with advanced citation-attribution or experiment requirements should test URL-level evidence, exports, and historical comparisons.
Moves from prompt and source gap to content action
Profound
Enterprise intelligence
Strong
Strong
Broad research and governance
Ahrefs Brand Radar
SEO research
Strong
Strong
Connects AI research with a large search/web dataset
Scrunch
Enterprise brand/web
Strong
Strong
Adds accuracy and agent-accessibility context
Bluefish
Enterprise marketing/commerce
Strong
Strong
Audience and product-level measurement
Peec
Lean marketing/agency
Good
Good
Clear dedicated reporting
Otterly
Small teams/consultants
Good
Good
Low-friction monitoring baseline
Semrush
Existing SEO-suite users
Good
Good
Consolidated SEO workflow
SE Visible
SE Ranking users/agencies
Good
Good
Familiar trend and client reporting
Do not compare vendor scores directly unless the prompt set, market, engine, frequency, and denominator are equivalent. A higher percentage from a smaller or easier sample is not necessarily better performance.
How to understand why a competitor appears more often
A useful LLM tracker should let you move through five layers:
Prompt: identify the exact audience, problem, comparison, or purchase intent where the competitor wins.
Answer: review the complete generated text and recommendation order.
Narrative: identify the attributes attached to the competitor, such as affordability, security, ease of use, or category leadership.
Sources: inspect the first-party and third-party URLs used as evidence.
Content gap: determine whether you lack a relevant page, original proof, consistent product facts, external validation, or crawlable structure.
This prevents the common mistake of treating every visibility gap as a request to publish another generic article. Sometimes the correct action is clearer documentation, a comparison page, a benchmark, a case study, product-feed repair, legitimate editorial outreach, or correcting inconsistent facts across existing pages.
RAG-driven visibility and citation tracking
When an answer engine uses retrieval-augmented generation, it may search or retrieve sources before composing the final response. Monitoring only the final brand mention misses important evidence. Track three separate outcomes:
whether the brand was mentioned;
whether an owned page was cited;
whether an external page describing the brand or a competitor was cited.
The source layer often explains why a brand is absent even when its own page is technically optimized. Ask vendors whether they preserve exact cited URLs, retrieval context, response text, timestamps, and model or surface details. “Source influence” inferred by a proprietary model should be labeled differently from an observable link in the answer.
Alerts and hallucination monitoring
Where a selected plan supports configurable alerts, connect each alert to reviewable evidence and confirm its delivery channel, trigger rules, and frequency. Otherwise, review these changes through scheduled monitoring:
a sharp decline in mention or citation rate across a stable prompt cluster;
an incorrect price, product capability, policy, executive, or market claim;
a new competitor replacing the brand in recommendations;
a high-risk negative narrative;
an outdated or harmful source appearing repeatedly;
loss of visibility after a website migration or content update.
Avoid reacting to one generated answer. LLM outputs vary, so require repeated observations and retain the baseline. A serious hallucination workflow should preserve the exact prompt, answer, engine, date, source, affected fact, severity, owner, and resolution status.
How to test accuracy before buying
Run the same proof of concept in two or three shortlisted tools:
Use at least three intent groups: category discovery, brand comparison, and problem-solving.
Include prompts where your brand should appear and prompts where it should not.
Compare the tool’s stored answer with a manual observation from the stated engine and market.
Check entity resolution for ambiguous brand names and product/sub-brand mentions.
Review false positives, missing citations, sentiment errors, and reordered recommendations.
Repeat prompts over time rather than using a one-day snapshot.
Export raw evidence and verify that another analyst can reproduce the report.
Connect the results to branded demand, qualified visits, assisted conversions, or pipeline without claiming unsupported causality.
Frequently asked questions
What is the best LLM tracking tool?
The nine tools compared here are Dageno AI, Profound, Ahrefs Brand Radar, Scrunch, Bluefish, Peec AI, OtterlyAI, Semrush, and SE Visible. Choose Dageno AI for monitoring connected to GEO work, Profound or Bluefish for enterprise programs, Ahrefs Brand Radar for broad research, and the remaining options according to evidence and reporting needs.
What is the difference between an LLM tracker and an AI rank tracker?
The terms often overlap. A robust AI rank tracker measures recommendation position, while an LLM tracker may also record mentions, citations, sources, sentiment, accuracy, complete answers, and competitor share. Always evaluate the evidence rather than the label.
Can LLM tracking tools show the exact ChatGPT or Gemini response?
Many products preserve the prompt and generated response, but coverage differs by engine, country, plan, and run type. Confirm whether you can inspect and export the exact response, timestamp, model or product surface, and cited URLs.
How can I track brand mentions in agentic search?
Build a stable prompt taxonomy, run it across the relevant answer and shopping agents, preserve responses, separate mentions from citations and recommendations, compare competitors, and segment results by market and audience. For shopping agents, also validate product-level and feed-level evidence.
Which metrics replace traditional keyword rankings?
Use mention rate, citation rate, recommendation position, share of voice, sentiment, factual accuracy, source share, and visibility by audience or intent. These complement rather than fully replace traditional rankings because AI answers and search results represent different discovery surfaces.
Can these tools monitor AI hallucinations?
Some platforms support accuracy or hallucination workflows. The strongest evidence is the exact incorrect claim linked to its prompt, response, engine, date, and source—not a single summary score. Human review remains necessary for material brand, legal, medical, financial, or product claims.
How often should LLM visibility be tracked?
Match frequency to decision speed. Daily tracking can help active campaigns and reputation risks; weekly tracking is often sufficient for content programs. Whatever frequency you choose, keep the prompts, engines, and markets stable enough to distinguish change from sampling noise.
Final recommendation
Start by defining the decision the data must support. If the goal is to find and close prompt, citation, and content gaps, choose Dageno. If the goal is enterprise intelligence and governance, compare Profound, Bluefish, and Scrunch. If the priority is an existing SEO dataset, evaluate Ahrefs Brand Radar or Semrush. For a focused pilot or agency report, compare Peec, Otterly, and SE Visible.
The best LLM tracking tool is not the one with the most impressive visibility score. It is the one that preserves enough evidence to explain what changed, why a competitor may be winning, and what your team should do next.
Ye Faye is an SEO and AI growth executive with extensive experience spanning leading SEO service providers and high-growth AI companies, bringing a rare blend of search intelligence and AI product expertise. As a former Marketing Operations Director, he has led cross-functional, data-driven initiatives that improve go-to-market execution, accelerate scalable growth, and elevate marketing effectiveness. He focuses on Generative Engine Optimization (GEO), helping organizations adapt their content and visibility strategies for generative search and AI-driven discovery, and strengthening authoritative presence across platforms such as ChatGPT and Perplexity