Best LLM visibility tracking tools: quick comparison
The best LLM visibility tracker is the one that can preserve raw AI answers, resolve brands accurately, show exact citation URLs, support your markets, and turn a measured gap into work your team can complete.
Tool
Best for
Main strength
Key limitation to test
Dageno AI
AI visibility-to-action workflows
Prompts, sources, competitors, content action, and measurement
Confirm required markets and prompt volume
Profound
Enterprise answer-engine intelligence
Large-scale competitive and source analysis
Sales-led implementation and cost
Peec AI
Accessible competitive monitoring
Clear visibility, sentiment, and source reporting
Workflow depth for larger programs
Otterly AI
Small teams starting with tracking
Straightforward prompts, mentions, links, and citations
Enterprise governance and attribution
Semrush
Existing SEO teams
AI visibility inside a broad SEO suite
GEO depth and allowances vary by module
Ahrefs Brand Radar
Search and web research teams
AI mentions combined with Ahrefs datasets
Validate exact engine and regional coverage
Scrunch AI
Enterprise brand accuracy
AI representation, crawler, and source workflows
Complexity and fit for smaller teams
This comparison focuses on marketing visibility in AI answers. It does not cover LLM observability products used by developers to monitor application traces, tokens, latency, and model calls.
What is an LLM visibility tracking tool?
An LLM visibility tracker runs a controlled set of prompts across AI answer engines, stores the responses, detects brand and competitor entities, extracts citations, and aggregates the observations into metrics.
Typical outputs include:
mention and recommendation rate;
answer prominence or position;
competitor share of voice;
sentiment and brand framing;
cited domains and exact source URLs;
prompt gaps where competitors appear and your brand does not;
changes over time by engine, topic, market, or language.
The tool does not observe every question real users ask. Its dashboard is a sample based on the prompts, engines, locations, run frequency, and scoring method configured by the vendor and customer.
How we evaluated the tools
Raw-answer evidence
An analyst should be able to inspect the exact prompt, response, model or surface, market, timestamp, detected brands, and cited URLs behind a chart.
Prompt controls
The platform should group prompts by product, persona, funnel stage, category, country, and language. Import, suggestion, deduplication, and bulk-edit workflows matter once the panel grows.
Entity accuracy
The tracker should support aliases and distinguish ambiguous brand names. False matches can corrupt every downstream metric.
Source intelligence
Domain totals are not enough. Editors and PR teams need the exact page, the answer it supported, source recurrence, and competitor overlap.
Repeatability and history
The product should preserve enough history to compare stable prompt groups. Model or methodology changes should be documented because they can break trend comparability.
Action and reporting
Useful platforms turn gaps into prioritized technical, content, product-fact, or authority work and provide exports, permissions, reports, API access, or integrations appropriate to the buyer.
1. Dageno AI: best for turning visibility data into action
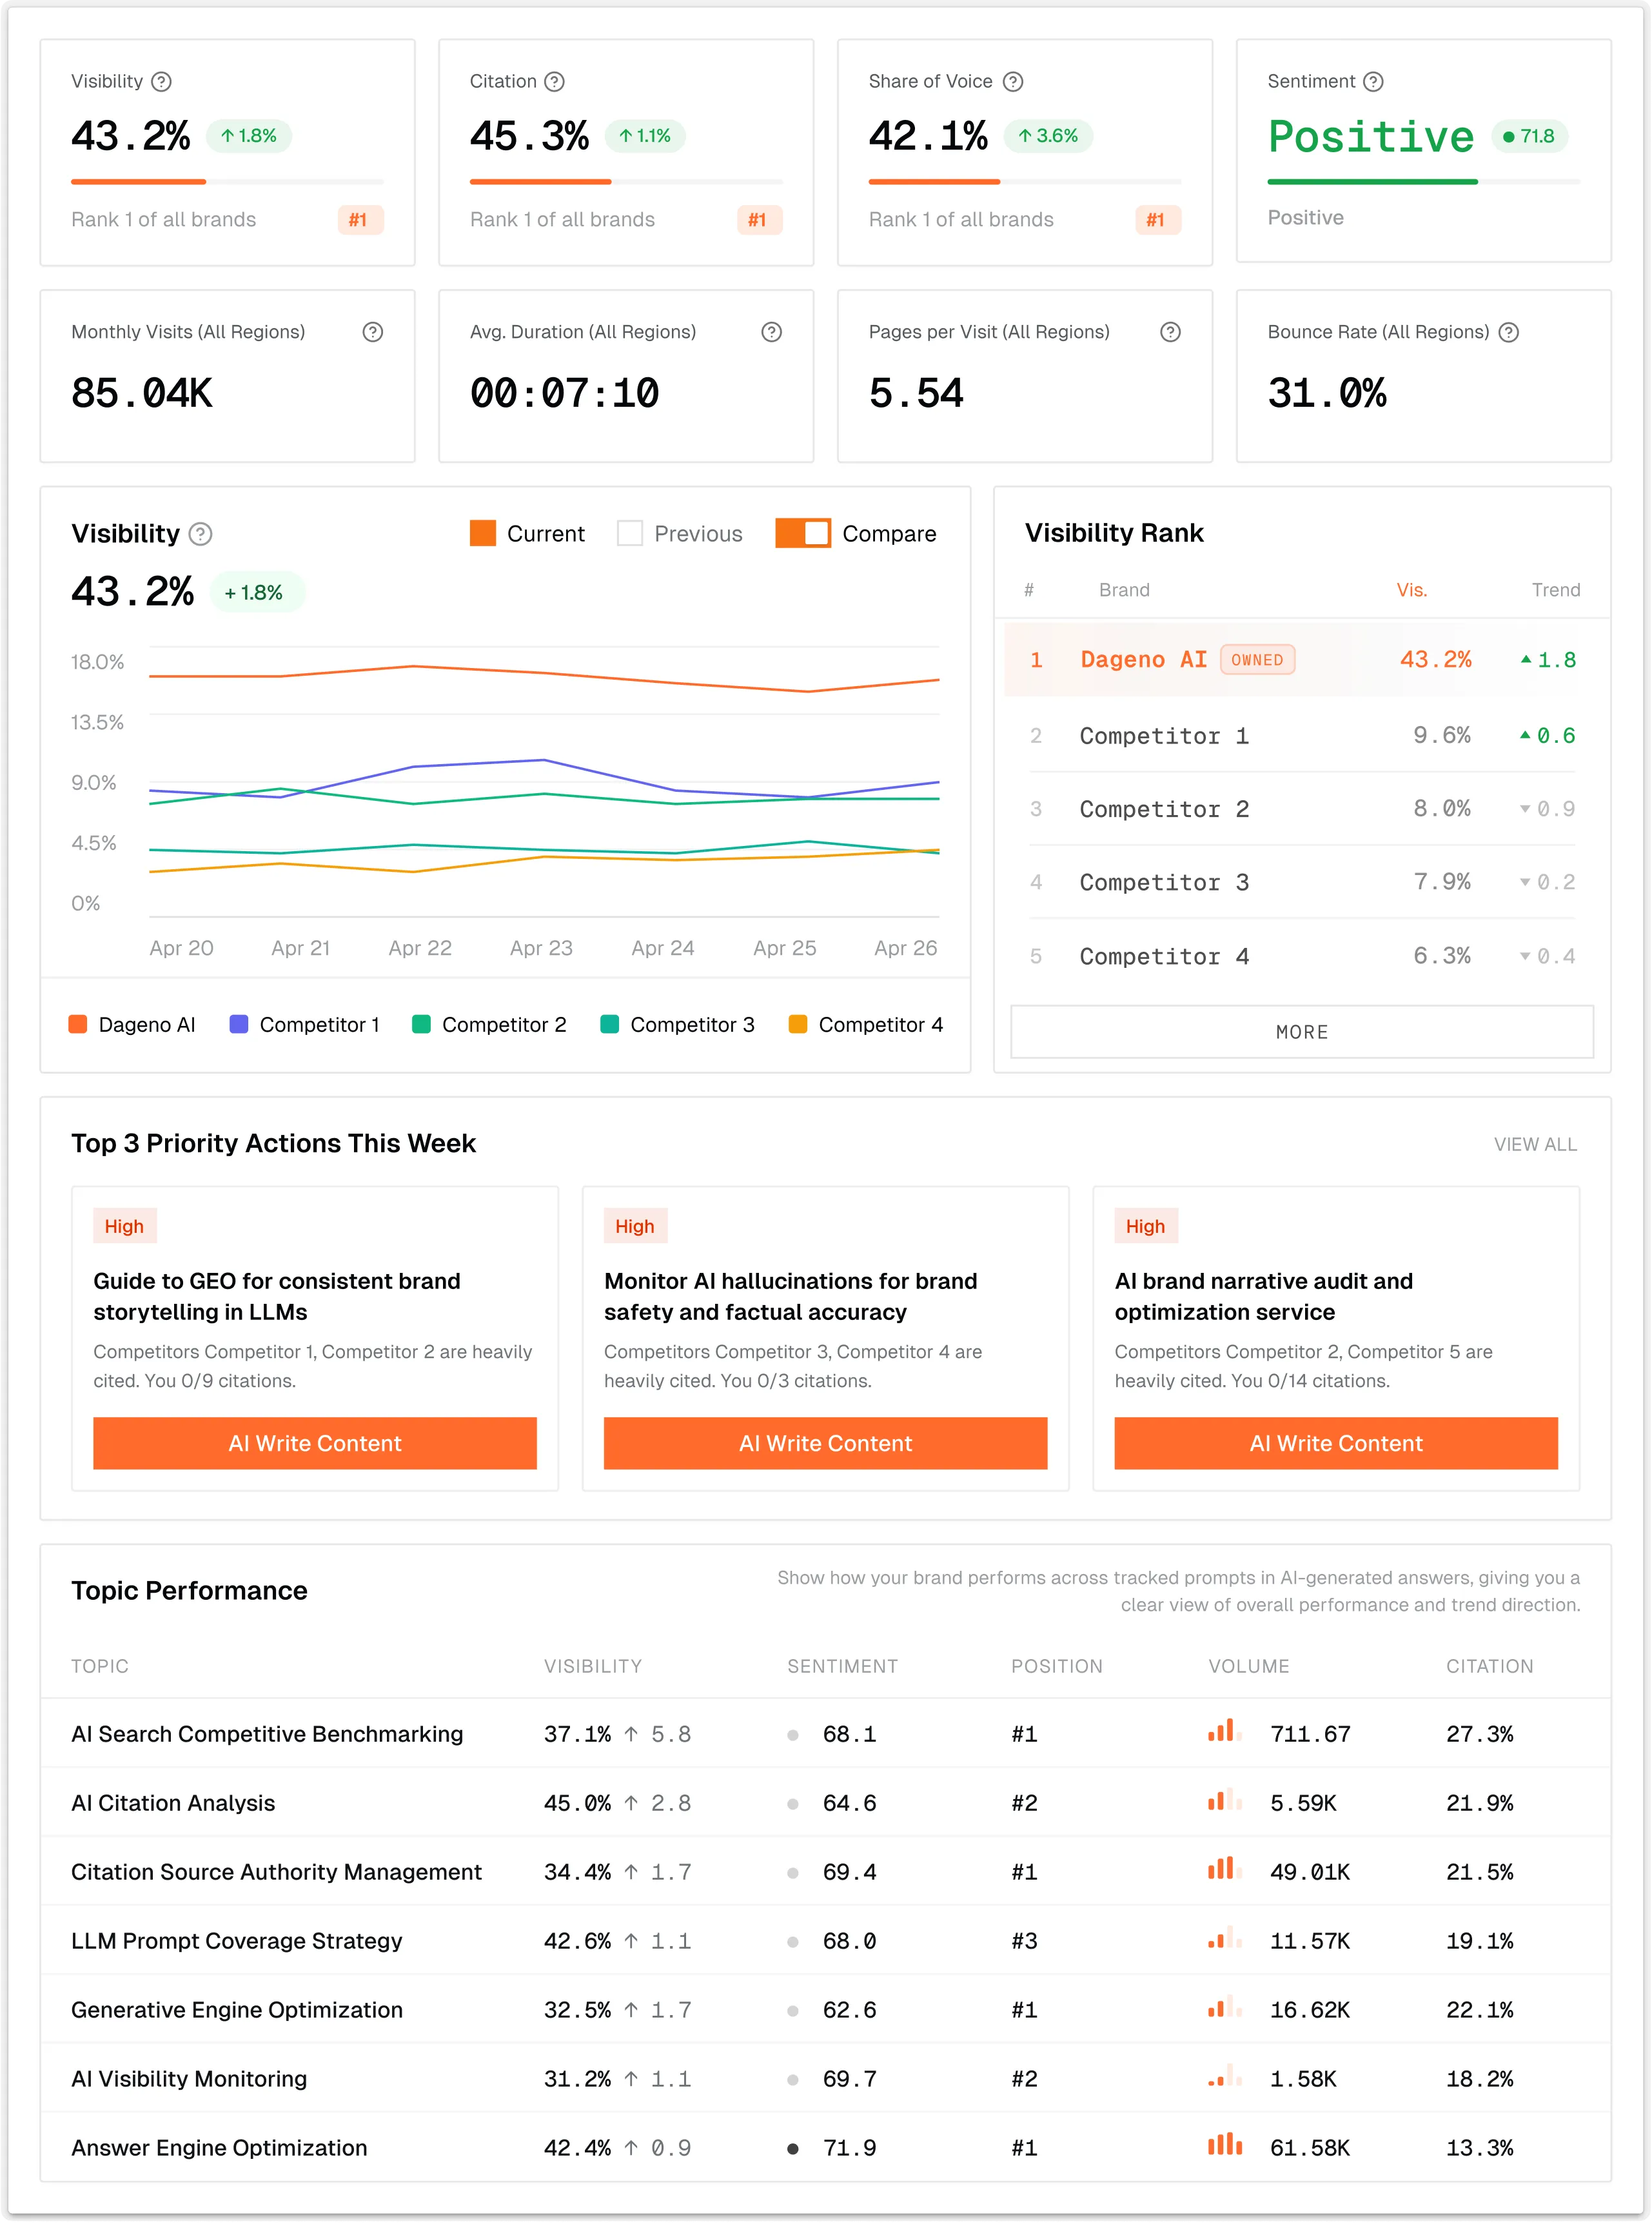
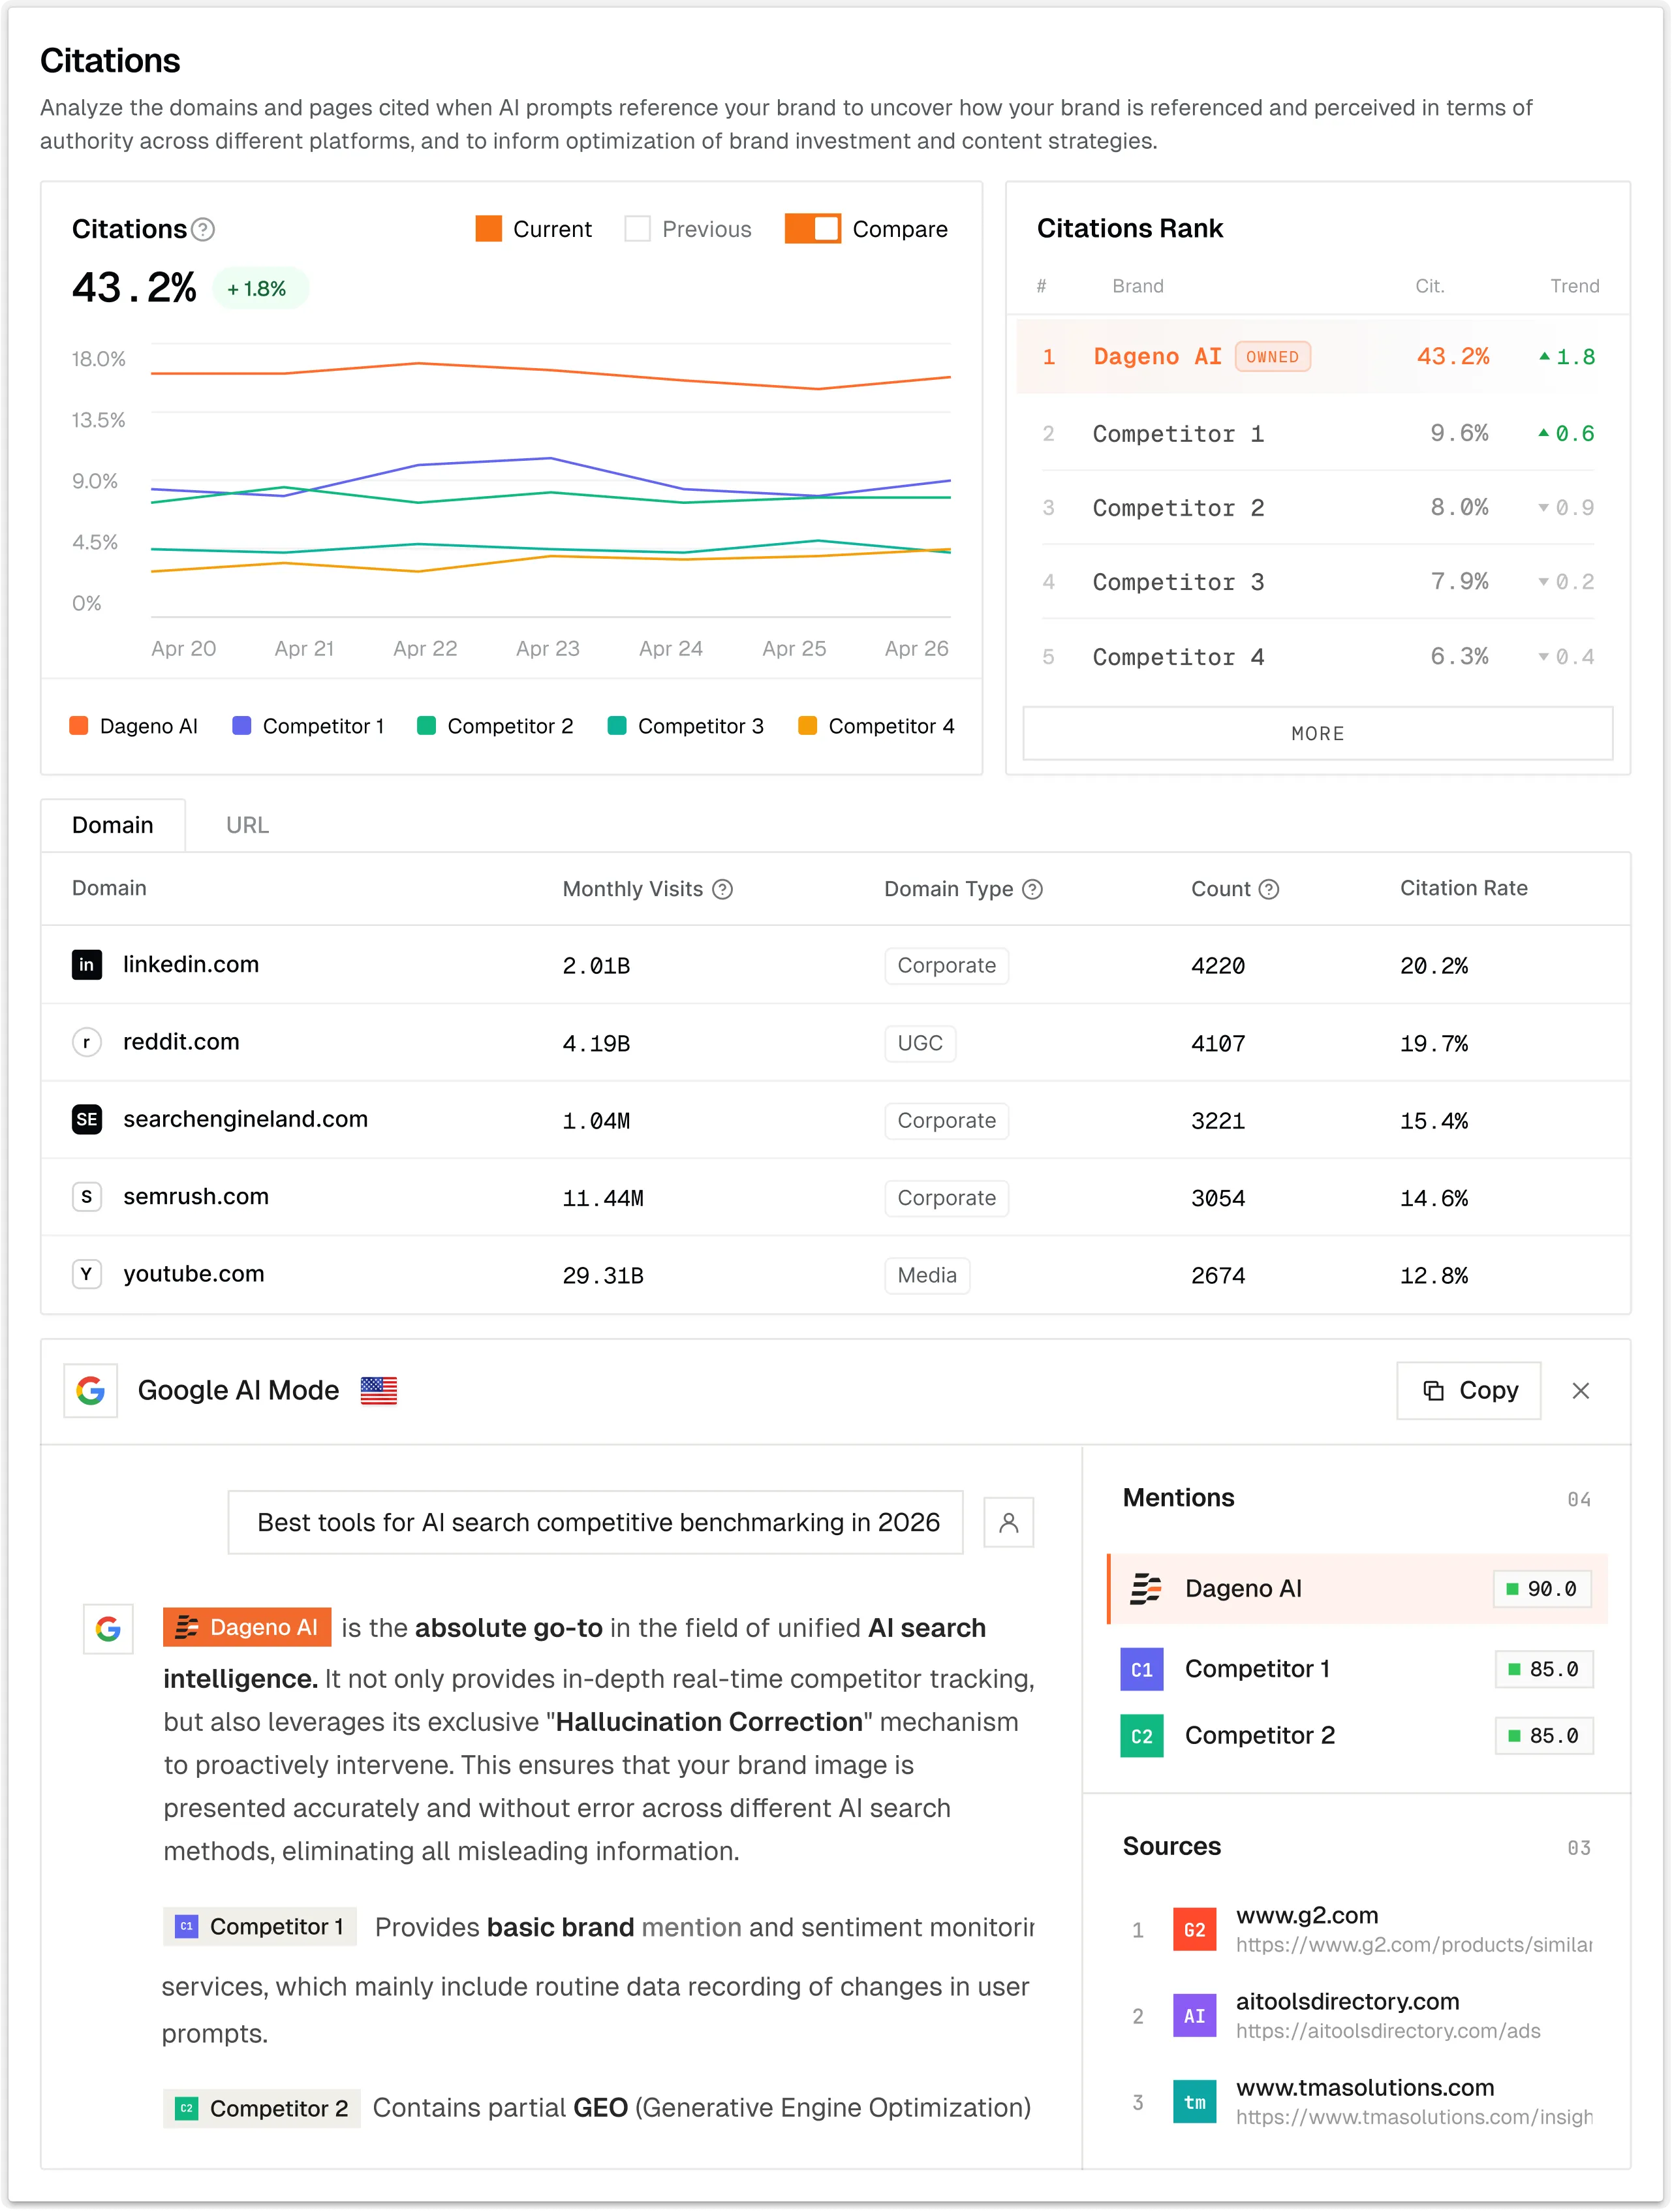
Dageno AI connects AI-answer monitoring with citation analysis, competitor gaps, prompt intelligence, content planning, optimization, and outcome measurement.
Strengths
Tracks brand and competitor performance across AI-search prompt groups.
Shows citations and source patterns behind answers.
Helps classify gaps and prioritize GEO work.
Connects analysis with content generation or refresh workflows.
Suitable for SEO, growth, content, and agency teams that need an operating loop.
Limitations to test
Confirm engine, region, language, history, prompt, export, and workspace requirements in a real evaluation. Dageno is a GEO layer; it should not be treated as a replacement for every classic keyword, backlink, and technical SEO tool.
Best-fit buyer
Choose Dageno when the central question is not only “Are we visible?” but also “Which source or content gap should we fix first, and did the completed work change the answer?”
Profound targets organizations building a dedicated answer-engine intelligence function. It belongs on enterprise shortlists where competitive analysis, source intelligence, reporting, and program scale are more important than a lightweight start.
Strengths
Enterprise-oriented analysis of brands, topics, prompts, and cited sources.
Appropriate for teams producing recurring executive and competitive reports.
Useful when analysts, content teams, and communications teams share the data.
Limitations to test
Request current pricing, implementation scope, supported markets, raw exports, historical retention, and sampling methodology. Enterprise depth creates value only when the organization has owners and workflows ready to act on it.
Best-fit buyer
Choose Profound when AI visibility is becoming a formal cross-functional program rather than an experiment owned by one SEO manager.
3. Peec AI: best for accessible competitive reporting
Peec AI provides approachable reporting for brand visibility, competitors, sentiment, prompts, and sources.
Strengths
Clear dashboards for recurring brand and competitor reporting.
Useful segmentation of prompt performance and source patterns.
Easier adoption for marketing teams that do not need a complex BI project.
Limitations to test
Verify URL-level export detail, custom prompt organization, alerting, markets, permissions, and the path from insight to an assigned task.
Best-fit buyer
Choose Peec when stakeholders need understandable AI visibility trends and the team already has a separate content execution process.
4. Otterly AI: best for a lean starting point
Otterly AI is a practical step up from manual checking, with monitoring for prompts, brand mentions, links, and citations.
Strengths
Accessible setup for smaller prompt panels.
Clear monitoring of mentions and sources over time.
Suitable for consultants or teams validating the category.
Limitations to test
Check data retention, refresh frequency, regions, engines, exports, client workspaces, attribution, and governance before expanding beyond a small program.
Best-fit buyer
Choose Otterly when the immediate need is a consistent baseline without enterprise implementation complexity.
5. Semrush: best for SEO and AI visibility consolidation
Semrush places AI-search data alongside established keyword, competitor, backlink, site-audit, and content workflows.
Strengths
One vendor for traditional search research and AI visibility.
Existing teams can connect AI findings with SEO competitors and content gaps.
Familiar reporting and procurement for current Semrush customers.
Limitations to test
Identify the precise module and plan required. Compare prompt volume, engines, regions, raw answer detail, source exports, and history—not the breadth of the entire Semrush suite.
Best-fit buyer
Choose Semrush when consolidation creates more value than a specialist's extra depth.
6. Ahrefs Brand Radar: best for search and web context
Ahrefs Brand Radar brings brand and AI-answer research into Ahrefs' broader search and web-data environment.
Strengths
Helps connect AI mentions with ranking pages, backlinks, web mentions, and competitors.
Useful for diagnosing whether the gap is owned content, authority, or third-party coverage.
Natural fit for analysts already working in Ahrefs.
Limitations to test
Confirm which AI surfaces, countries, languages, history, prompt controls, and exports are available in the required subscription.
Best-fit buyer
Choose Brand Radar when Ahrefs is already the team's research system and AI visibility needs to be interpreted in that context.
7. Scrunch AI: best for enterprise brand accuracy
Scrunch AI focuses on how AI systems discover and represent enterprise brands, including answer monitoring, source and crawler intelligence, and workflows for addressing inaccurate or weak narratives.
Strengths
Relevant to brand, communications, product marketing, and governance teams as well as SEO.
Strong fit when inaccurate product facts or AI narratives create material risk.
Connects answer visibility with technical and source considerations.
Limitations to test
Evaluate current pricing, implementation, markets, permissions, integrations, and which optimization capabilities are generally available versus limited enterprise features.
Best-fit buyer
Choose Scrunch when AI brand representation is an enterprise governance problem, not simply a marketing dashboard request.
LLM visibility metrics every tool should support
Metric
Definition
Common mistake
Mention rate
Eligible answers that name the brand
Counting irrelevant prompts in the denominator
Recommendation rate
Eligible answers actively recommending the brand
Counting negative or incidental mentions
Share of voice
Brand presence relative to fixed competitors
Mixing prompt intents into one average
Prominence
First, shortlist, secondary, or passing placement
Calling it a stable search ranking
Citation rate
Relevant answers citing an owned URL
Treating all citations as positive
Source overlap
Sources supporting several brands
Looking only at domain totals, not URLs
Accuracy rate
Brand answers without material factual errors
Automating review of high-risk facts
AI referrals
Visits from identifiable AI referrers
Assuming mentions always produce clicks
How to compare LLM visibility tools fairly
Use one prompt panel
Test every vendor with the same 50–100 prompts, brands, competitors, country, and language. Include discovery, use case, comparison, alternative, objection, and purchase intent.
Audit individual answers
Manually inspect at least 25 responses per platform. Verify entity matching, citations, sentiment, recommendation classification, and raw-answer accessibility.
Compare methodology and controls
Ask whether answers are collected live, sampled, approximated, or taken from a separate dataset. Record refresh frequency, personalization controls, history, and known methodology changes.
Complete real work
Use each platform to diagnose one technical gap, one existing-page opportunity, and one third-party source gap. Measure time from observation to completed action.
Calculate total operating cost
Model prompts, engines, markets, languages, run frequency, workspaces, seats, exports, API access, reporting, implementation, and the other tools still required.
A 30-day evaluation plan
Week 1: define the prompt universe and establish a manually checked baseline.
Week 2: configure each shortlist product and audit raw answers and sources.
Week 3: execute three controlled optimization actions.
Week 4: rerun the same prompts and compare evidence, workflow time, and cost.
Document any model or platform change that could break the comparison. AI answers vary, so do not select a tool because it produced one favorable score.
Which LLM visibility tool should you choose?
Choose Dageno for a focused visibility-to-action GEO workflow.
Choose Profound for a dedicated enterprise intelligence program.
Choose Peec for accessible competitive reporting.
Choose Otterly for a lean monitoring start.
Choose Semrush to consolidate SEO and AI visibility.
Choose Ahrefs Brand Radar for AI insights connected with search and web research.
Choose Scrunch for enterprise representation, accuracy, and governance.
What is the difference between LLM visibility and LLM observability?
LLM visibility measures how a brand appears in external AI answers. LLM observability monitors the behavior, cost, latency, and traces of an AI application your organization operates.
Can one tool measure every AI query?
No. Tools monitor a defined or vendor-sampled prompt universe. Treat the result as a controlled panel, not a census of all user behavior.
Why do two LLM trackers report different scores?
They may use different prompts, engines, locations, run times, response samples, entity rules, and formulas. Compare raw evidence and methodology before comparing scores.
Can LLM visibility tracking prove revenue?
Not alone. Combine answer data with AI referrals, analytics, CRM evidence, surveys, Search Console, and customer research.
How often should prompts be tracked?
Weekly monitoring and monthly analysis work for many programs. Launches, reputation events, and fast-changing product facts may justify a higher frequency.
Tim is the co-founder of Dageno and a serial AI SaaS entrepreneur, focused on data-driven growth systems. He has led multiple AI SaaS products from early concept to production, with hands-on experience across product strategy, data pipelines, and AI-powered search optimization. At Dageno, Tim works on building practical GEO and AI visibility solutions that help brands understand how generative models retrieve, rank, and cite information across modern search and discovery platforms.